Opening · slides 1–9
Day 1 · slides 1–9
When does an AI output justify action?
The opening slides introduce the lecturer, the guiding question and what you will be able to do by the end of Parts 1–3.
Follow along: Slides 1–9 in the browser PDF handout
Artificial Intelligence in Cybersecurity · Parts 1–3 · Machine learning for threat detection: foundations, evaluation and limits. Per-Arne Andersen, Associate Professor, Department of Information Systems, University of Agder.
Parts 1–3 follow the slides in order. Each slide heading gives the slide numbers, so you can read it beside the slides. Where a slide builds up step by step on the projector, the Part page shows its final state and lists the same steps with the same numbers. Where a slide runs a real computation, the page embeds an interactive version: Step moves one state forward, Run plays the rest, Reset starts again, and the selector changes the data or the setting.
| Part 1 | Part 2 | Part 3 |
|---|---|---|
| How does a model learn from data? · paradigms, pipeline, representation · demo: fit a score, set a threshold | Is the detector useful? · how many alerts are real, and can analysts keep up? · demo: change the threshold | Where do evaluations and AI tools mislead? · pitfalls, drift and LLMs · cases: AI-enabled threats |
One guiding question runs through the lecture: when does an AI output justify action? Each part opens with the question it answers and closes with a one-line answer, each example teaches one idea, and the summary, the last main slide, answers the guiding question. The recurring phishing example uses the lookalike domain mail.exampIe.com (capital I, U+0049, in place of the lowercase l, U+006C). exampIe.com is a real, registrable domain: it appears here only as text, and nothing here claims that its owner is malicious. Cited studies and incidents are real. No malware is executed in the labs. Keep employer secrets and live credentials out of the exercises.
Meet the lecturer · slides 1–5
Slides 1–5 · About the lecturer
The cover (slide 1) states the lecture's guiding question: When does an AI output justify action?
Per-Arne Andersen is an Associate Professor in the Department of Information Systems at the University of Agder, Norway. He is affiliated with CIEM, the Centre for Integrated Emergency Management. The question linking his work to this course is how can we understand a learned decision, and use it responsibly?
His previous employers are NTT Security (managed security services) and Telenor Cyberdefence (cybersecurity services for organisations). These descriptions characterise the organisations' services, not personal roles. Security practice supplies a recurring teaching question: what evidence justifies the next action?
Sources: per-arne.no · University of Agder profile · organisation context: NTT Security · Telenor Cyberdefence.
Project descriptions and illustrations: per-arne.no. The images are the public project illustrations, not screenshots of running systems, results or security validation.
Both research questions come back in security: what did we measure, and what justifies an action? In reinforcement learning (RL), an agent learns from feedback on its actions. Slides 21–23 return to RL.
Slide 5 shows a practical tool, Poengtavla, a public web project that sits beside the research toolkit and learning experiments. The teaching link is that a system's purpose and the next action should be easy to understand. The slide shows only the public landing page, not authenticated functionality or an AI benchmark.
The course question · slides 6–9
Slide 6 · Which tools do you use?
The opening poll asks which security tools you have worked with:
| Short name | Full name | What it does |
|---|---|---|
| EDR | Endpoint Detection and Response | Monitors endpoint devices and supports response on them. |
| UEBA | User and Entity Behavior Analytics | Looks for unusual user or device behaviour. |
| SIEM | Security Information and Event Management | Brings security events together for analysis. |
Or email filtering? Who uses a large language model (LLM) in security work? During the lectures, interrupt with questions and bring your operational experience. Slides and references follow after class.
Terminology: NIST CSRC Glossary, Endpoint Detection and Response and SIEM tool · IBM, User and Entity Behavior Analytics [industry].
Slide 7 · When does an AI output justify action?
| Parts 1–3 · AI for security | Parts 4–6 · Security of AI |
|---|---|
| 1. Machine-learning foundations | The AI system itself becomes the asset under attack. |
| 2. Detection and its evaluation | |
| 3. Methodological pitfalls | |
| 4. LLMs and AI-enabled threats |
Parts 1–3 treat AI as a tool of the defender (and briefly of the attacker). Parts 4–6 treat the AI system itself as an asset that can be attacked. Both days serve one course question, when does an AI output justify action?, through two sub-questions:
- Question 1 · interpret the output: What does a score of 0.73, or an LLM’s draft, actually tell us about this case?
- Question 2 · justify the decision: Which independent check, and whose approval, must come before we block, isolate or report? (the evidence and controls needed before acting)
The two days build towards one answer. A detector's score is limited evidence, and its value depends on the base rate and on how the detector was evaluated. Unverified or unevaluated LLM text is a proposal, not evidence. LLM output evaluated like a detector (the F_1-scored trial on slide 59) inherits the same base-rate logic, and output reproduced against an independent record (the Firefox CVEs on slide 63) becomes evidence.
Slide 8 · What you will be able to do
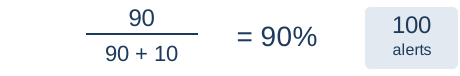
In full, by the end of Parts 1–3 you should be able to:
- Explain how supervised and unsupervised learning turn security data into a detector, and what the choice of representation implies.
- Calculate precision and daily alert load from detection rate, false-positive rate and base rate, and justify an operating threshold.
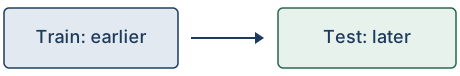
- Critique a published or vendor evaluation of an ML detector against known methodological pitfalls, and propose a sounder evaluation design.
- Assess where large language models add value to security operations, and the risks they introduce, including their use by attackers.
The slide cuts each example to a few words. In full: why does a 02:14 sign-in from a new device raise an alert without proving an attack? Is the vendor’s “99.8% accuracy” measured on future test data, or on near-duplicates? An assistant proposes “isolate W17”: what evidence and controls do you need? The 99.8% figure is a claim written for this course, not a reported result of any product. A new laptop is unusual for an unsupervised detector but can still be legitimate, for example a planned replacement.
Slide 9 · Today in three parts
One guiding question (the title) and three part questions, one per part:
- Part 1 · How does a model learn from data? Paradigms, pipeline, representation. Demo: fit a score, set a threshold.
- Part 2 · Is the detector useful? How many alerts are real, how many attacks it misses, whether analysts can keep up. Demo: change the threshold.
- Part 3 · Where do evaluations and AI tools mislead? Pitfalls, drift and LLMs; cases of AI-enabled threats.
The part dividers repeat these questions word for word, and each part closes with a one-line answer. The summary, the last main slide, returns to all three questions and answers the guiding question. The table at the top of this page gives the times.